Readable
A pipeline is a set of short YAML manifests that anyone on the team can review in a pull request. No Python glue to maintain.
 Hydra ETL

Open source · AGPL-3.0 · Python 3.9+
Hydra ETL turns data pipelines into readable YAML. Check them with one command, then run them from the
terminal, a REST API or a visual editor, with a single pip install and nothing else to deploy.
pip install "hydra-etl[server]" Then run hdrctl serve: Studio and API open on localhost:5678. No Node, no database, no broker.
A pipeline is a set of short YAML manifests that anyone on the team can review in a pull request. No Python glue to maintain.
hdrctl validate checks sources, steps, types and destinations before a single row is read or written.
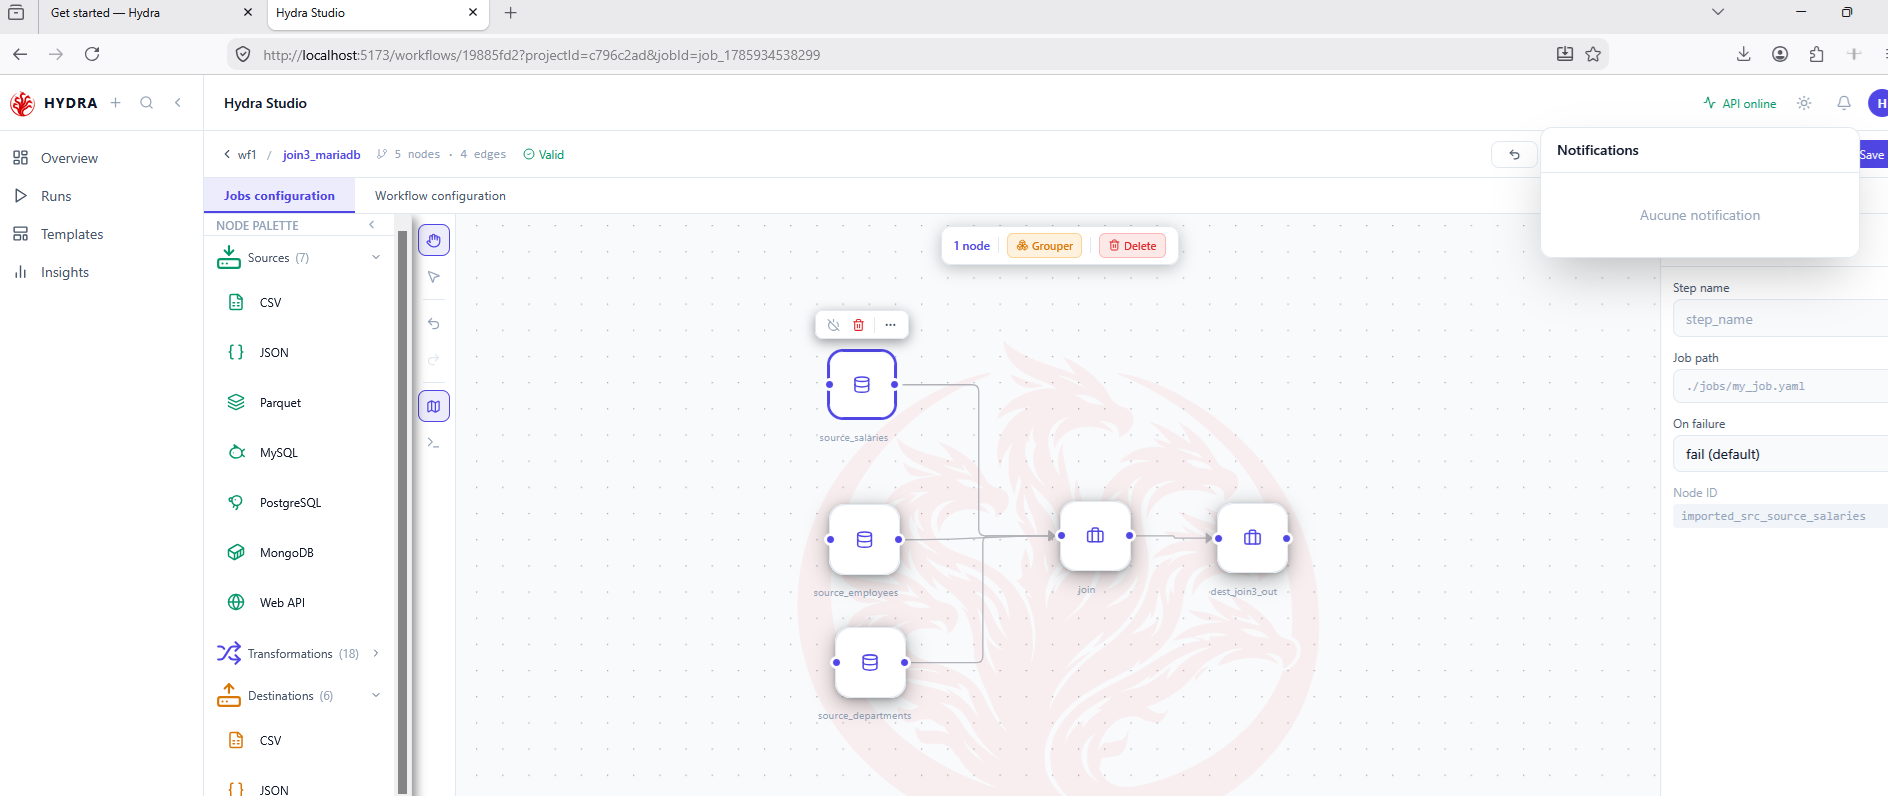
The same manifests run from the terminal, a REST API or the visual Studio. Build with the mouse, get YAML out.
A job connects one source to one destination through an ordered list of transformations. Each manifest answers a single question: where the data comes from, how it is reshaped, where it goes, and which source feeds which destination.
sources.yaml: where the data comes fromtransformations.yaml: how it is reshapeddestinations.yaml: where it goespipeline.yaml: which source feeds which destinationversion: "1.0"
steps:
- cast:
mapping:
amount: float
- filter:
expr: "amount > 0"
- aggregate:
by: [name]
agg:
total: { func: sum, col: amount }hdrctl init my_job # scaffold from a template
hdrctl validate my_job # strict checks, no data touched
hdrctl run my_job # executeScaffold, validate, test and run jobs from a terminal or a CI pipeline.
Design jobs and workflows on a canvas, served by the same process.
DAGs with dependencies, parallel branches, retries, cron triggers and actions.
One small YAML language for sources, transformations and destinations.
Edit and run Hydra pipelines in your browser, nothing to install.
Completion and live validation for manifests inside the editor.
Connectors
Engines
AI-ready: Hydra ships an MCP server. Claude, Cursor or VS Code can write pipelines, and Hydra validates them before anything runs.
Hydra targets file-and-database pipelines that should stay readable and run without extra infrastructure. It is not a replacement for every tool below.
| Tool | Pipelines defined in | Scope | To get started | Comparison |
|---|---|---|---|---|
| Hydra ETL | YAML | Extract, transform, load + workflows | pip install hydra-etl | |
| Airflow | Python | Orchestration | Scheduler, webserver, metadata DB | Airflow vs Hydra |
| dbt | SQL + YAML | Transform in the warehouse | A data warehouse | dbt vs Hydra |
| Airbyte | UI / config | Extract & load | Docker / Kubernetes | Airbyte vs Hydra |
| Dagster | Python | Orchestration | Python code + daemon | Dagster vs Hydra |
| Prefect | Python | Orchestration | Python code + server or cloud | Prefect vs Hydra |